The Whole Pipeline in One File a Human Can Actually Read
Part 4 of 4: How a data engineering harness eliminates the AI coding agent errors that survive review.
Introduction
"Why do I need that? Isn't Claude Code good enough?"
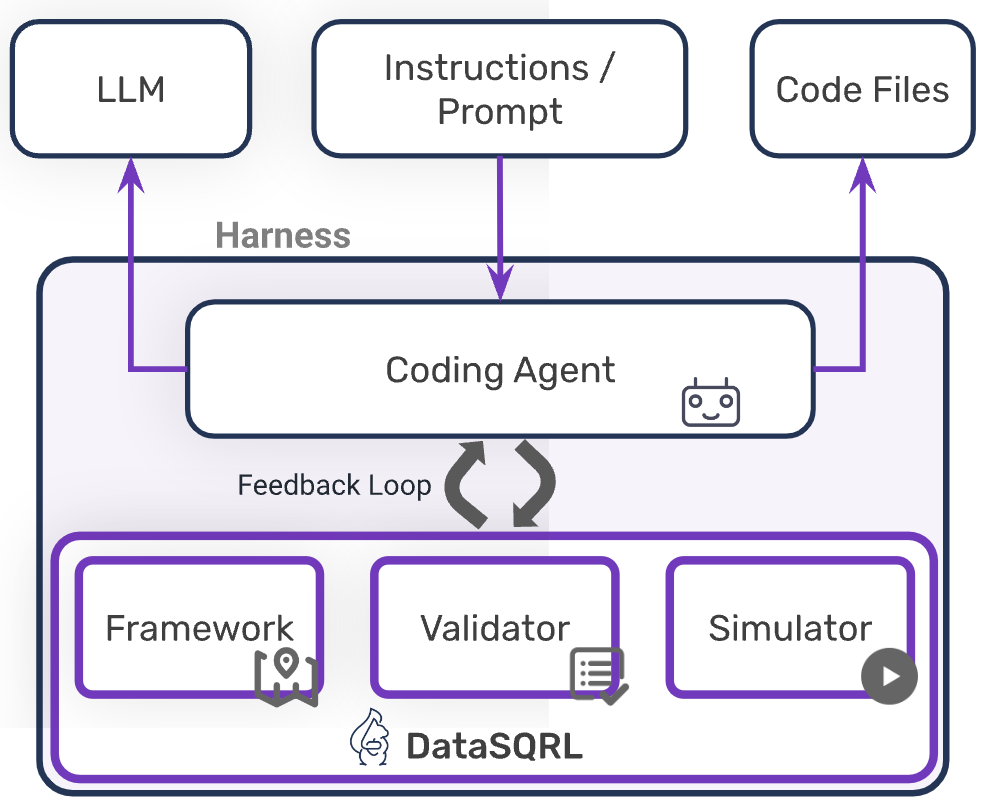
We get that question a lot. We are building an open-source data engineering harness, the tooling and guardrails that a coding agent uses to build data pipelines. Claude Code, Codex, and OpenCode already write plausible data pipeline code. So what is the harness for?
Parts 1, 2, and 3 were about generating the pipeline, validating it, and testing it. Part 4 is about the check that cannot be automated away: a person understanding what the pipeline actually means.
When an agent builds a conventional pipeline, the logic ends up spread across dozens or hundreds of files in two or three languages. Ingestion scripts, transformation jobs, table definitions, glue, API resolvers. Nobody holds that in their head. So the bugs where every line is correct and the meaning is wrong slip through, and the human review that was supposed to be the last line of defense collapses under fatigue.