Avoiding Duplicate Processing in Flink SQL Streaming Jobs

Flink SQL is a powerful abstraction layer that unifies batch and stream processing over semi-structured data. It extends the widely used SQL language with streaming constructs such as tumbling windows, session windows, and, more recently, process table functions. This enables non-experts in streaming technologies to express complex real-time data processing logic succinctly.
As a result, Flink SQL significantly lowers the barrier to entry for building real-time data systems.
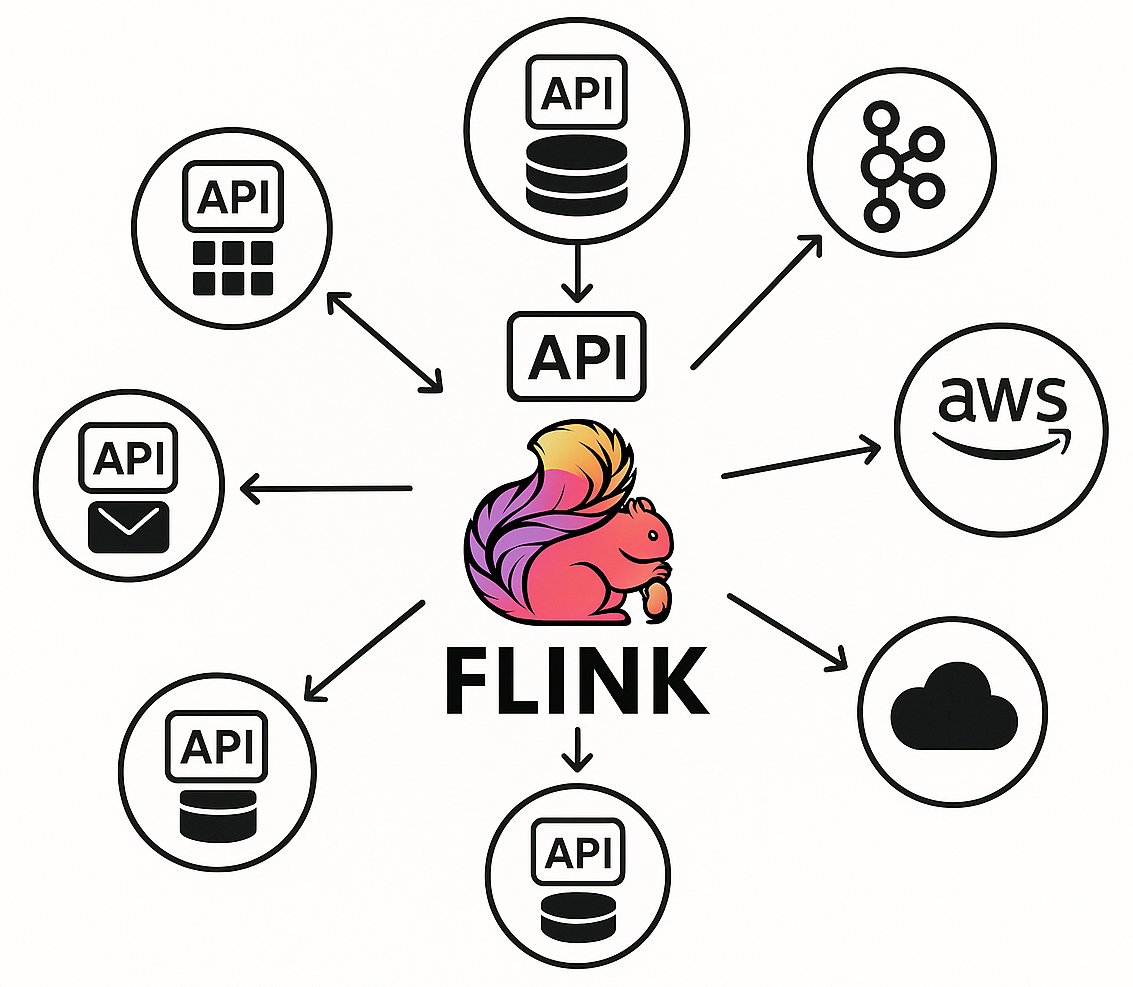
However, developing streaming applications differs fundamentally from traditional SQL query processing. One key difference is that streaming jobs often have multiple sinks populated by a single pipeline, sharing large portions of common data processing logic.
While Flink SQL provides mechanisms to express this concisely—using views and statement sets—in practice, this often results in duplicate processing in the generated job graph.